
Here’s how warehouse sizing usually actually happens. Someone spins up a new warehouse and runs a few queries. They notice it’s a little slow during the busiest hour of the week, so they bump it up a size to be safe. Maybe two sizes, just in case. That size then becomes “the size” for good. Nobody worked out what the warehouse actually needs most of the time. It was just good enough for the worst hour, once. Often it becomes official enough to end up in the name itself – etl_warehouse_l, analytics_xl. That quietly locks the decision in even further, since changing the size now means the name stops matching reality too. Nobody wrote the original decision down anywhere, and nobody’s really the owner of revisiting it later. From then on, it’s just what the warehouse runs as, and what everyone calls it.
This article is part of our guide to Snowflake warehouse optimization. For what each size costs, see Snowflake warehouse sizes and credits per hour.
The problem is that the worst hour isn’t most hours. A warehouse sized for Monday morning’s load runs at that size all day Tuesday, all weekend, every quiet night in between. Whenever it is running, it pays for capacity that’s only earning its keep for a sliver of the week. The rest of the time, it has far more capacity than the work needs. Yet the price tag assumes it’s always busy. Multiply that by every warehouse your team has ever sized this way – and most teams have more than one. Then “a bit oversized, just in case” turns into a real, ongoing cost that nobody consciously chose to pay. Nobody makes this mistake on purpose. It’s just what happens when sizing is a one-time guess instead of something that keeps up with reality.
And that’s before the generation question even comes up
On top of picking a size, there’s also a generation to pick. Most teams have never had a clean way to know which one actually fits a given workload. Gen2 warehouses often perform better for the same size on the right kind of workload. But you can’t eyeball “the right kind of workload” from a dashboard. And most people don’t have time to go test it properly. So teams either stick with whatever they started on, or guess. Once they make a guess, they rarely revisit it. Revisiting it means setting aside real time to test, compare, and second-guess a decision that already feels settled.
Why this almost never fixes itself
In theory, someone could go back through every warehouse every few months. They could check the actual usage pattern and re-tune the size and generation by hand. In practice, that almost never happens. Not because it isn’t worth doing, but because it competes with everything else on a data team’s plate. And a warehouse that’s “working fine” never feels urgent enough to interrupt that for. So the guess from day one keeps running quietly for as long as the warehouse exists – name and all.
SmartPulse takes the guessing out of sizing
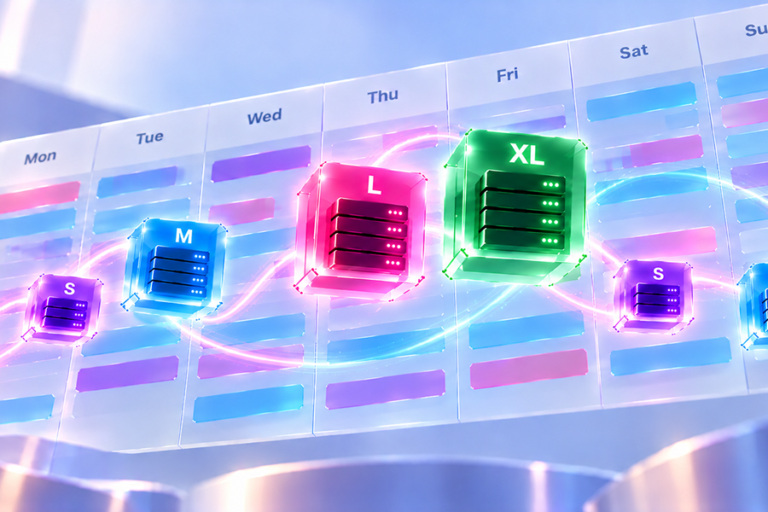
SmartPulse looks at how your team actually uses a warehouse, hour by hour, instead of trusting a size someone picked once. It then builds a schedule around that: bigger when the load calls for it, smaller the rest of the time. The schedule applies once you approve it. It keeps re-checking the real pattern of usage and surfaces updates for you to accept as that pattern changes. It doesn’t freeze in place the moment someone decided “this seems fine” and moved on. SmartPulse makes the size-and-generation call the way it should have worked from the start. It bases the call on what’s actually happening on the warehouse right now, not on a guess nobody reconsidered. SmartPulse schedules warehouses that have a predictable usage pattern. If a warehouse’s usage is too irregular to forecast, it doesn’t get an automatic schedule. That way you always know which warehouses SmartPulse covers.
You choose how it optimizes
SmartPulse runs in one of two modes, so the tradeoff is yours to set, not assumed for you. Cost mode leans toward the leanest size that still handles the work. Performance mode leans the other way, favoring headroom so queries stay fast even as load shifts. You can also set an SLO, so the schedule respects the performance bar you actually need, not a generic default. Either way, SmartPulse hands you a ready-to-review plan, listing the size and generation changes, before anything takes effect. Then you make the call. Accept the schedule as it stands, or lean it further toward savings or performance, depending on what that warehouse needs. Once it is running, Seemore reports savings warehouse by warehouse, so you can see the effect on your bill.
It doesn’t ignore sudden spikes
Alongside the hourly schedule, SmartPulse includes Burst Protector. It watches for queueing that the scheduled size can’t absorb. It then scales the warehouse up within seconds and back down once the spike passes. Burst Protector also has its own modes, so you decide how aggressively it steps in when something unusual happens. That way a warehouse doesn’t stay undersized the moment traffic breaks from the normal pattern.
You can see exactly what it’s doing
None of this runs as a black box. You approve the schedule before it takes effect. If you want to override something yourself, you can also set static time slots manually for any warehouse. You can see exactly who activated SmartPulse on a given warehouse. You can also follow everything it does through Seemore’s event log and real-time monitoring. That leaves a clear, visible record of what changed and when.
And when you know something’s coming, you can step in
Sometimes you know in advance – or notice on the spot – that a warehouse must handle something unusual. Then switch on Live Tuning and set the warehouse’s configuration yourself for 5 minutes to 24 hours. SmartPulse’s schedule pauses for that time and picks up again from the current hour slot when Live Tuning ends.
Frequently asked questions
What is Seemore Data's SmartPulse automation?
SmartPulse is Seemore’s automation for Snowflake warehouse sizing. It builds an hourly schedule from how you actually use a warehouse, instead of a fixed size someone picked once. Once you approve it, SmartPulse keeps the schedule current, adjusting size and generation to match real usage.
Why is manually picking a Snowflake warehouse size wrong?
Because usage isn’t constant. A size chosen to comfortably handle the busiest hour of the week ends up oversized for every quieter hour. And that is most of the week. Picking one fixed size means either overpaying most of the time or risking slowdowns at peak. And most teams never go back to re-check the decision.
What’s the difference between Snowflake Gen1 and Gen2 warehouses?
Gen2 is Snowflake’s newer generation of standard warehouses and is now the default for new ones in most regions. It uses more credits per hour than Gen1: 1.35 times on AWS and GCP, 1.25 times on Azure. So it only saves money when queries finish fast enough to make up the difference. Most teams don’t have time to test which generation fits each warehouse. So SmartPulse recommends the generation alongside the size, and you only take on Gen2’s extra cost when it pays for itself. Our Gen1 vs Gen2 comparison goes deeper.
Does SmartPulse favor cost savings over performance, or the other way around?
You choose. SmartPulse runs in Cost mode, which leans toward the leanest size that still handles the work. Or it runs in Performance mode, which favors extra headroom so queries stay fast even as load shifts. You can also set an SLO, so the schedule respects the specific performance bar that warehouse actually needs.
How do I know what a schedule will actually do before I approve it?
SmartPulse hands you a ready-to-review plan with the size and generation changes it proposes. The schedule doesn’t take effect until you approve it. You can adjust the settings to lean further toward savings or performance. You can also set static time slots yourself for any part of the schedule. Once it is running, Seemore reports savings warehouse by warehouse.
What happens if there’s a sudden, unexpected spike in load?
That’s what Burst Protector is for. It runs alongside the regular schedule and watches for queueing the scheduled size can’t absorb. Then it scales the warehouse up within seconds, so traffic that breaks the usual pattern doesn’t leave a warehouse undersized. Burst Protector has its own modes too, so you can set how aggressively it should step in.
Does SmartPulse just run on its own with no visibility into what it’s doing?
No – every change is visible. You approve the schedule before it takes effect, and you can see exactly who activated SmartPulse on a given warehouse. You can also follow everything it does through Seemore’s event log and real-time monitoring.
What if a warehouse needs to handle something unusual, like a product launch or a big one-time job?
Switch on Live Tuning and set the warehouse’s configuration yourself for a fixed time, from 5 minutes to 24 hours. SmartPulse’s schedule pauses for that time and picks up again from the current hour slot when Live Tuning ends.
Is this only about saving money, or does it help with performance too?
Both. SmartPulse balances the two, not just cost. That’s why it has Cost and Performance modes, an SLO setting, a ready-to-review plan before any schedule applies, and per-warehouse savings reports.
Do I need to babysit SmartPulse once it’s running?
No – that’s the point of automating it. But it’s not a black box either. You approve the schedule before it applies, and Burst Protector handles sudden spikes on its own within the mode you set. You can check the event log or real-time monitoring whenever you want. You can also step in manually with static time slots or Live Tuning whenever a specific situation calls for it.


