Snowflake’s pricing model charges for compute, storage, and cloud services separately, making Snowflake cost control more complex than most teams anticipate. Virtual warehouses spin up fast, queries run across massive datasets, and cloud services layer charges accumulate quietly in the background. Without the right tooling, engineers end up spending hours firefighting anomalies that proper observability would have surfaced in minutes.
This guide covers the Snowflake cost management tools available in 2026, with a feature-by-feature breakdown to help CDOs, lead data engineers, and FinOps practitioners find the right fit. Each platform is evaluated on primary focus, automation capabilities, root cause analysis depth, and pricing.
How do Snowflake cost optimization tools reduce compute spend?
Snowflake cost optimization tools reduce compute spend by identifying inefficiencies and enabling teams to take corrective action across warehouses, pipelines, and downstream usage, including:
- Identifying expensive or frequently executed queries
- Detecting underutilized or oversized virtual warehouses
- Highlighting unused tables, pipelines, and dashboards
- Exposing cost and usage anomalies across teams and workloads
- Prioritizing optimization efforts based on real usage impact
More advanced platforms extend beyond observability by automating recommendations, detecting anomalies in real time, and using AI-driven insights to connect cost, performance, and data lineage across the entire data stack.
The three categories, and why the distinction matters
Most tools in this space fall into one of three groups, and the group matters more than the feature list:
- Efficiency-focused. Improve query and warehouse efficiency within Snowflake. Meaningful savings in targeted areas, but typically without end-to-end context across pipelines, lineage, and business usage.
- Cost-focused. Reduce Snowflake spend quickly, usually through automated warehouse behaviour. Fast, but narrow.
- Full-stack. Connect cost to the pipeline that generated it and the dashboard that consumed it, so optimization is grounded in what the business actually uses.
A finance-heavy team may need allocation first. A platform team may need query analysis first. A lean engineering team often needs action first, because nobody has spare hours for daily tuning.
Quick verdict
- Best overall for autonomous cost reduction: Seemore Data. Combines end-to-end lineage, automated warehouse management, and AI-powered root cause analysis to reduce Snowflake spend by an average of 33% across the customer base, reaching 70% at peak.
- Best for multi-cloud attribution: Finout. Strong for teams managing Snowflake alongside AWS, GCP, or Azure who need unified cost attribution in a single dashboard.
- Best for tuning: SELECT.dev. Practical warehouse-sizing guidance and query analysis for teams who want to tune manually.
- Best for enterprise scheduling: Slingshot (Capital One). Structured warehouse scheduling controls at enterprise scale.
Tool comparison
| Tool | What it optimises | Acts on its own | Root cause | Pricing |
| Seemore Data | Full stack, ingestion to BI | Yes | Full, with lineage | Custom |
| Keebo | Snowflake cost | Yes | Minimal | Custom |
| Espresso AI | Snowflake cost | Yes | Limited | Custom |
| Slingshot (Capital One) | Warehouse scheduling | On a schedule | Limited | Custom |
| Yuki Data | Snowflake cost | Yes | Limited | Custom |
| SELECT.dev | Queries and tuning | No | None | Subscription |
| Altimate AI | SQL and dbt | No | Limited | Custom |
| Finout | Multi-cloud attribution | Limited | None | Usage-based |
| Chaos Genius | Anomalies, observability | No | Partial | Open source / paid |
| Metaplane | Data quality | No | Partial | Custom |
| Snowflake native | Built-in controls | Auto-suspend only | None | Included |
In-depth reviews
1. Seemore Data
Overview. Seemore Data is an autonomous context-aware data engineering platform that continuously analyzes and optimizes cost, performance, and usage across the modern data cloud. It connects Snowflake spend to upstream tools like Fivetran and dbt, and downstream BI like Tableau and Looker, providing full-stack visibility and automated action in a single platform.
Standout features
- End-to-end context: links every Snowflake cost to the dashboard triggering the query, the pipeline feeding it, and the team responsible. No other tool on this list maps cost to lineage at this depth.
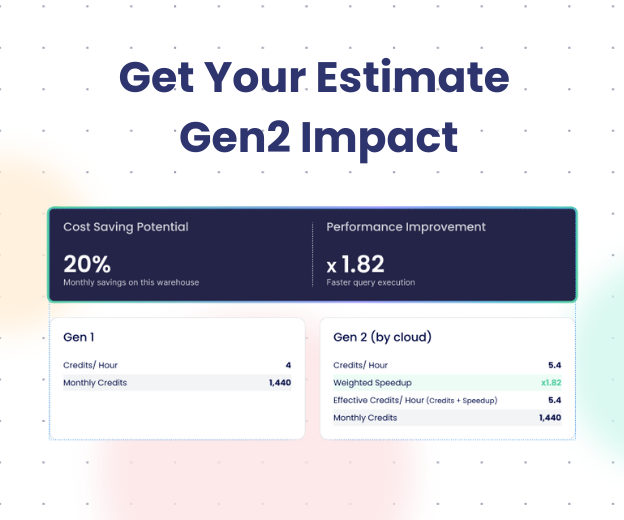
- Smart Pulse: dynamically resizes virtual warehouses hourly based on real usage patterns and transitions workloads to Gen2 automatically.
- Auto Shutdown: suspends idle compute beyond Snowflake’s native auto-suspend, eliminating waste at the minute level.
- AI-powered auto clustering: recommends optimal clustering keys based on real workload and query patterns, reducing full-table scans without manual tuning.
- Auto Scaler: adjusts warehouse size and concurrency in real time to balance cost and performance.
- Anomaly detection and AI root cause analysis: when a spend spike occurs, the AI agent explains the cause immediately, for example a dbt model frequency change, reducing investigation time from hours to seconds.
- Query optimization: context-aware recommendations grounded in full lineage and real workload impact.
Pros
- Only platform combining full-stack lineage with autonomous warehouse management
- An average of 33% cost reduction across the customer base, reaching 70% at peak
- Covers Fivetran, dbt, Tableau, and Looker in a single context graph
- Significantly reduces engineering time spent on cost firefighting
Cons
- Pricing is not publicly listed; requires a demo or assessment call
- Full value is most apparent in complex, multi-tool data stacks; smaller or simpler environments may not need the full capability set
2. Keebo
Focus: autonomous cost optimization for Snowflake and Databricks.
Keebo leans into Snowflake warehouse and workload tuning. Teams that care most about compute behaviour and performance trade-offs often put it on the list.
Strengths:
- Continuous warehouse tuning through automated optimization
- Query routing to distribute workloads more efficiently
- Always-on optimization requiring minimal manual intervention
- Clear fit for teams chasing warehouse waste
Limitations:
- Cost-first design with limited observability depth
- Minimal end-to-end lineage or business context
- Optimization primarily centred on warehouse behaviour
- Narrower coverage outside the warehouse layer
Best suited for: organizations prioritizing automated compute efficiency over system-wide insight.
3. Espresso AI
Focus: ML-driven Snowflake cost optimization.
Strengths:
- Automated warehouse autoscaling and intelligent scheduling
- Query rewriting aimed at improving runtime efficiency
- Aggressive cost-reduction positioning with rapid initial savings claims
Limitations:
- Narrow focus on cost reduction without deep observability or usage context
- Limited pipeline, lineage, and BI visibility
- Less comprehensive warehouse governance controls
- Newer entrant with limited long-term enterprise validation
Best suited for: teams seeking quick, tactical cost reductions with minimal setup.
4. Slingshot (Capital One)
Focus: warehouse scheduling and compute efficiency.
Strengths:
- Scheduling-based warehouse optimization
- Emphasis on balancing cost and performance
- Enterprise-grade tooling developed by Capital One
Limitations:
- Primarily focused on scheduling rather than continuous optimization
- Limited autonomous decision-making beyond predefined rules
- Lacks deep observability, lineage, and business usage context
Best suited for: large enterprises seeking structured warehouse scheduling controls.
5. SELECT.dev
Focus: Snowflake warehouse and query efficiency with strong cost visibility.
Strengths:
- Practical guidance for warehouse sizing and configuration
- Query performance analysis with optimization recommendations
- Visibility into Snowflake compute usage across workloads
- Native dbt integration supporting analytics engineering workflows
Limitations:
- Limited end-to-end lineage compared to observability-first platforms
- Optimization remains largely manual rather than autonomous
- Minimal proactive anomaly detection or root-cause explanation
- Focuses on Snowflake in isolation without full pipeline or BI context
Best suited for: teams looking to improve Snowflake efficiency through hands-on tuning and education.
6. Yuki Data
Yuki Data focuses on automated Snowflake and BigQuery cost reduction with a metadata-first setup. It is attractive when a team wants fast time to value and low lift on onboarding.
Strengths:
- Metadata-first connection
- Query and warehouse action paths
- Automation around cost reduction
- Fast onboarding motion
Limitations:
- Narrower than platforms that connect BI, orchestration, and lineage in one place
- Less broad operating context for teams with messy stack ownership
7. Altimate AI
Focus: AI-assisted SQL optimization and dbt development acceleration.
Strengths:
- Automated SQL optimization suggestions
- Tight integration with dbt Power User for development workflows
- Helpful performance insights for individual Snowflake queries
Limitations:
- Narrow scope centred on query-level tuning
- Limited warehouse-level optimization and scheduling
- Minimal cost governance, anomaly detection, or lineage depth
Best suited for: analytics engineering teams focused on improving dbt models and SQL performance.
8. Finout
Overview. Finout is a multi-cloud cost management platform that consolidates and analyzes cloud spending across providers, including Snowflake. It is best suited for teams managing Snowflake alongside AWS, GCP, or Azure who need unified cost attribution without deep data-stack observability.
Standout features: unified cloud cost dashboard, cost attribution by team, project or query, custom budget alerts, spending visualizations.
Pros: strong multi-cloud coverage, quick to set up, intuitive cost grouping and allocation.
Cons: limited Snowflake-specific depth, with no query-level or warehouse-level automation. No lineage or root cause analysis for Snowflake cost spikes. Better suited as a complementary tool than a standalone Snowflake optimization solution.
9. Chaos Genius
Overview. Chaos Genius is an open-source tool offering automated anomaly detection and cost insights for Snowflake, with a focus on alerting teams before problems escalate.
Standout features: automated anomaly detection, detailed cost reports across compute, storage and cloud services, query optimization insights, integrations beyond Snowflake.
Pros: open-source tier is accessible for teams with limited budgets, good anomaly detection speed and configurable alerting, useful for catching unexpected charges early.
Cons: no autonomous optimization or warehouse automation. Lineage limited to ETL-level, with no BI connectivity. Requires significant manual follow-up after alerts.
10. Metaplane
Focus: data quality observability with cost insights. Partial pipeline lineage, no warehouse automation. Pricing on request.
Overview
Metaplane is a data observability platform focused on data quality and pipeline reliability, with cost monitoring as a secondary capability. It helps teams ensure data operations are trustworthy and efficient by monitoring pipeline performance and alerting on quality issues.
Standout Features
- Data Observability: Monitors data quality and pipeline performance across the stack.
- Cost Insights: Surfaces areas where compute and storage costs can be reduced.
- Automated Alerts: Flags data quality issues that may cause inefficient query patterns.
- Lineage Visibility: Maps data flows to help pinpoint expensive operations.
Pros
- Strong data quality monitoring alongside cost visibility
- Good for teams where data reliability and cost control are equally important
- Pipeline lineage helps contextualize certain cost issues
Cons
- Cost management is secondary to data quality; Snowflake-specific cost features are limited
- No warehouse automation or autonomous actions
- Less suited for teams whose primary goal is Snowflake spend reduction
11. Snowflake native cost management
Snowflake’s own tooling covers more than teams often realise, and is the correct starting point before buying anything:
- Cost Management Interface (Snowsight). Built-in spend visibility.
- Budgets. Spend thresholds with notification.
- Resource Monitors. Hard limits that can suspend warehouses.
- Snowflake Trail. Observability across queries and pipelines.
Strengths: included with Snowflake, no procurement, native auto-suspend and auto-resume.
Limitations: no lineage, no root cause analysis, and no cross-stack context. It tells you that spend rose, not why.
Which approach fits your problem
| If your problem is… | Look at | Where it falls short |
| Spend is rising and nobody can say why | Full-stack platforms that trace cost across ingestion, transformation and BI | More than you need if you only run Snowflake and already know where the cost sits |
| Specific queries and warehouses are inefficient | Query and warehouse tuning tools | Improves what you point it at; will not find the problem for you, and needs engineering time |
| The bill needs to come down this quarter | Cost-reduction automation | Fast and narrow. Cuts spend without explaining it, so the same waste returns |
How to choose
- Decide whether you need allocation, analysis, or action. A finance-heavy team may need allocation first. A platform team may need query analysis first. A lean engineering team often needs action first, because nobody has spare hours for daily tuning.
- Review your last three cost spikes. Ask which tool would have caught them, and how quickly.
- Check stack reach. Does it see the pipeline and the dashboard, or only the warehouse?
- Test automation guardrails. Automated action is only useful if you can constrain it.
- Compare proof, not promise. Ask for the mechanism behind a savings number, not just the number.
Snowflake Cost Optimization Best Practices
Reducing Snowflake spend requires more than enabling auto-suspend. The practices below address the architectural decisions that drive the largest cost inefficiencies.
1. Right-Size Virtual Warehouses Using T-Shirt Sizing
Snowflake virtual warehouses scale in T-shirt sizes (XS through 6XL), and each increment doubles credit consumption per hour. Most teams default to larger warehouses to avoid query timeouts, but this creates chronic overspend during low-concurrency periods.
The right approach is to match warehouse size to query complexity and concurrency requirements. Ad hoc analytical queries often run efficiently on XS or S warehouses. ETL pipelines with high data volume benefit from M or L, but should use multi-cluster configurations to handle concurrency spikes rather than permanently running a larger single-warehouse size. Running workload profiling for two to four weeks before locking in warehouse sizing prevents over-provisioning that compounds into significant monthly waste.
2. Implement Clustering Keys on High-Scan Tables
Snowflake stores data in micro-partitions, each containing between 50 MB and 500 MB of uncompressed data. Without clustering keys, queries that filter on non-sequential columns must scan far more micro-partitions than necessary, resulting in significant increases in compute consumption.
Clustering keys tell Snowflake how to organize micro-partitions relative to specific column values. For tables frequently filtered by date, region, or another high-cardinality dimension, clustering dramatically reduces the number of micro-partitions scanned per query. The trade-off is reclustering cost: Snowflake continuously re-clusters data in the background as new rows arrive, which consumes cloud services credits. Teams should evaluate clustering keys only on tables with high query frequency and large data volume. For tables under 1 TB or queried infrequently, clustering adds cost rather than reducing it.
3. Use Materialized Views Strategically
Materialized views pre-compute and store query results as physical data objects. Unlike standard views, which re-execute their underlying query on every call, materialized views serve results directly from cached storage. This reduces compute for repeated, complex aggregations, particularly for downstream BI tools running the same queries repeatedly against large tables.
The cost consideration: Snowflake charges for maintaining materialized views as base table data changes. If the underlying table updates frequently and the materialized view is queried infrequently, maintenance costs will outweigh the compute savings. Materialized views are most cost-effective for stable, high-frequency read patterns. Standard views remain the right choice for queries that run rarely or where the base data is highly dynamic.
4. Monitor and Control the Cloud Services Layer
The cloud services layer covers query compilation, authentication, metadata management, and transaction handling. Snowflake provides this at no additional cost up to 10% of daily compute credits. Usage above that threshold is charged separately and often goes unnoticed until it appears on the monthly bill.
Teams running high volumes of short, frequent queries (common in Snowpipe ingestion patterns or BI tools with aggressive refresh schedules) are most exposed to cloud services overage. Auditing ACCOUNT_USAGE.QUERY_HISTORY for queries with very short execution times and high cloud_services_credits_used values identifies the workloads responsible. Batching small queries, reducing refresh frequency in BI tools, and using result caching to avoid redundant query compilation are effective mitigations.
5. Optimize File Sizes for Snowpipe and Batch Ingestion
Snowflake performs best when ingested files fall between 100 MB and 250 MB in uncompressed size. Files smaller than this create excessive micro-partition fragmentation, which increases query scan costs downstream. Files larger than this slow ingestion and limit parallelism.
For Snowpipe users, this typically means buffering data upstream (in S3, GCS, or Azure Blob Storage) before triggering ingestion, rather than loading every micro-batch as it arrives. For batch jobs, splitting or merging files to hit the target size range is worth the engineering investment, given the downstream query cost reduction.
6. Enforce Budget Controls with Resource Monitors
Resource monitors allow teams to set credit quotas on virtual warehouses at the account, warehouse, or custom level, and trigger automated actions (notify, suspend, suspend immediately) when thresholds are crossed. Most teams set monitors at the account level but skip warehouse-level controls, which leaves individual runaway warehouses unchecked until the account-level threshold is hit.
Setting warehouse-level resource monitors with notify thresholds at 75% and suspend thresholds at 100% of the expected weekly credit budget creates early warning and automated control. Pairing this with a documented alert escalation path ensures anomalies get resolved quickly.
7. Conduct Regular Usage Audits
Snowflake’s ACCOUNT_USAGE schema retains 365 days of historical data across queries, warehouses, storage, and data sharing. Monthly audits using QUERY_HISTORY, WAREHOUSE_METERING_HISTORY, and TABLE_STORAGE_METRICS identify patterns that automated tools may not surface: tables that were expensive six months ago and are now unused, warehouses sized up for a one-time project and never resized down, or pipelines whose business owners have changed.
Combining usage data with business context (which requires lineage-aware tooling) is what separates cost awareness from actionable cost reduction.
The Optimal Snowflake Optimization Journey
Effective Snowflake cost management follows a progression from visibility to accountability to automation. Teams that treat it as a periodic project rather than a continuous engineering practice consistently struggle to sustain savings.
Step 1: Observability with Context
Basic observability shows which queries are expensive. Contextual observability shows which downstream dashboards are triggering those queries, which teams own them, and whether the business outcome justifies the spend.
A table with terabytes of unclustered data supporting a rarely viewed dashboard looks like a query cost problem in isolation. With lineage, it becomes clear whether the dashboard is driving meaningful business outcomes or consuming compute for no real reason. That distinction changes the remediation path entirely.
Step 2: Ownership and Monitoring
Cost problems persist when no one is accountable for them. Monitoring should cover user behavior patterns, pipeline anomalies, and domain-level budget trends, as well as warehouse activity.
Root cause analysis tools close the loop between anomaly detection and resolution. An unexpected ETL cost spike traced to a recent query change with inefficient joins is fixable in hours when lineage connects the alert to the source. Without that connection, engineers spend days investigating.
Step 3: Continuous Optimization
Optimization aligned with actual usage patterns is more durable than one-off tuning efforts. Right-sizing warehouses for off-peak periods, refactoring queries based on real workload data, and archiving unused datasets all compound over time into sustained cost reduction.
The highest-value optimization insight most teams share: cost management performs best when it is built into the engineering workflow, not treated as a periodic cleanup exercise.
Maximize Efficiency with Strategic Snowflake Cost Optimization
Effective Snowflake cost management is a continuous process that requires the right combination of tools, architectural discipline, and usage accountability. Seemore Data leads the field by combining end-to-end observability, full-stack lineage, and autonomous optimization into a single platform. Paired with Finout for multi-cloud cost attribution, Chaos Genius for anomaly alerting, and SELECT.dev for targeted query tuning, data teams can build a complete cost control practice that scales with their stack.

Frequently asked questions
What are the best Snowflake tools for cost optimization?
The best Snowflake cost management tools combine cost monitoring, usage attribution, and actionable recommendations. Native Snowflake features provide basic visibility, but most data teams rely on external platforms to understand who is driving costs, why spend is increasing, and where optimizations can safely be applied across warehouses, pipelines, and BI usage. Based on automation depth and lineage coverage, Seemore Data and Finout are the most commonly evaluated options in 2026.
How do the features of the top Snowflake cost management tools compare?
The feature comparison matrix at the top of this guide maps the six leading platforms across primary focus, auto-scaling capability, root cause analysis depth, and pricing model. The key differentiator across the field is whether a tool provides observability only, or combines observability with autonomous action and full-stack lineage. Seemore Data falls into the latter category; Finout is strong within specific domains but narrower in scope.
Why is Snowflake's native cost monitoring not enough?
Snowflake’s native tools show what you spent, not what caused it. They lack deep lineage, usage context, and cross-tool visibility. Without knowing which dashboards, pipelines, or teams are triggering compute, cost optimization stays reactive and manual.
How do Snowflake cost optimization tools reduce compute spend?
Most tools start with observability, helping teams identify where compute is being consumed. More advanced platforms add anomaly detection, automated warehouse management, usage-based recommendations, and AI-driven root cause analysis powered by deep data lineage. The most effective tools enable continuous optimization across the entire data stack, rather than focusing only on query-level tuning or warehouse metrics.
What is the difference between warehouse optimization and stack-wide optimization?
Warehouse optimization focuses on query performance and warehouse sizing. Stack-wide optimization covers the full data flow, including ingestion, transformations, warehouses, and BI usage, to eliminate waste that warehouse-only tools cannot detect, such as abandoned dashboards or redundant pipelines.
Can Snowflake cost optimization be automated?
Yes. Modern platforms automate anomaly detection, warehouse resizing, budget monitoring and alerts, and root cause analysis using data lineage. Automation reduces costs continuously without requiring manual audits or ongoing firefighting.
How do data teams measure ROI from Snowflake cost optimization tools?
ROI is typically measured through reduced Snowflake compute credits, elimination of unused data assets, fewer engineering hours spent on troubleshooting, and better cost attribution across teams and projects. Teams often see measurable savings within weeks once usage-level visibility is in place.
Are Snowflake cost optimization tools safe to use in production?
Yes. Leading tools operate on metadata and usage patterns, not on actual data. This allows teams to optimize costs without impacting data integrity, performance, or security.