AI agents can now write your SQL and pipelines. The checks around them need to cover spend, not just accuracy.
A growing share of the SQL running in our warehouses wasn’t typed by a person. It came from a copilot in the IDE, an agent building a dbt model, or a natural-language “ask your data” interface sitting in front of Snowflake or Databricks. I think that’s mostly a good thing. But it changes what we need to check before code reaches production.
The conversation so far has focused on correctness. Does the query return the right rows? Does the new model break a downstream dashboard? Those are the right first questions. There’s a second question that gets asked far less often: is this the right query at the right price?
An agent can write SQL that’s perfectly correct and still costs ten times more than it should. If our guardrails only check accuracy, we’re automating the creation of expensive queries.
Let the model think, let code decide
The pattern I see working in AI-assisted data engineering is a simple split. The language model handles the parts that are hard to formalize: understanding intent, planning the approach, writing the first draft. Deterministic code handles the parts that should have one right answer, the same every time.
You already have a lot of that deterministic layer. Schema checks. Lineage and impact analysis. Tests like dbt’s data tests, which assert things such as uniqueness, non-null values, and accepted values, and either pass or fail. You don’t want a model “deciding” whether a primary key is unique. You want a check that answers the question the same way every run.
The point is that an LLM’s output is a proposal, and proposals get verified by something that doesn’t hallucinate. That principle is sound. My argument is that the verification layer is incomplete if it stops at correctness.

The model proposes. Deterministic checks, including cost, decide.
The research already measures efficiency. Most teams don’t.
Academic text-to-SQL benchmarks figured this out a while ago. The BIRD benchmark, published in 2023 by researchers from the University of Hong Kong, Alibaba DAMO Academy and others, was built on 95 databases totaling 33.4 GB. It added a metric most earlier benchmarks lacked: the Valid Efficiency Score, which rewards SQL that is both correct and fast. A query that returns the wrong answer scores zero, however quick it is. A correct query gets credit relative to how efficiently it runs.
Two findings from that paper stuck with me:
- When the authors took correct queries generated by ChatGPT and had experts rewrite them using standard optimization rules, run time dropped by 77.75% on average, with identical results. That was a small sample of 10 examples, but the direction is clear. “Correct” left a lot of efficiency on the table.
- In their analysis of 500 sampled ChatGPT errors, the most common category was wrong schema linking (41.6%), where the model picked the wrong tables or columns. Close behind was misunderstanding database content (40.8%). In other words, ChatGPT struggled most with context, not syntax.
Model quality has moved a lot since 2023, so I wouldn’t read those accuracy numbers as current. But the structural lesson holds: correctness and efficiency are separate properties, and you have to measure both.
What cost guardrails actually look like
The good news is that the data platforms already expose much of what you need to build cost checks that are deterministic, cheap to run, and easy to automate.
Estimate before you execute. In Snowflake, EXPLAIN compiles a statement without running it, and it doesn’t need a running warehouse. The plan includes partitionsTotal, partitionsAssigned and bytesAssigned for each table scan. Snowflake describes the assigned values as upper-bound estimates, and compiling still uses a little cloud services compute. That’s enough to flag an agent’s query that’s about to scan every partition of a fact table. In BigQuery, a dry run validates the query and estimates bytes processed. It uses no slots and isn’t charged. Google does warn that dry runs on tables with row-level security always return 0 bytes.
Size the warehouse, not just the query. Snowflake bills compute by warehouse size and running time, per second with a 60-second minimum on each resume, and each size step roughly doubles credits per hour. An agent that “fixes” a slow query by bumping the warehouse to the next size has made a cost decision. That should be an explicit, reviewable change, not a side effect.
Put hard limits under everything. Snowflake resource monitors can notify, suspend, or suspend immediately when a warehouse hits a credit threshold within a daily, weekly or monthly interval. Two caveats from the docs: monitors don’t cover serverless features or AI services (Snowflake points to budgets for those), and they’re not meant for precise, hourly control. Snowflake suggests buffers, like suspending at 90% rather than 100%. Give agents their own warehouses and their own monitors, so a runaway loop hits a ceiling instead of your monthly bill.
Make the check a gate, not a report. The pattern that works for tests works for cost. A CI step that runs EXPLAIN or a dry run on new and changed models, compares estimated scan size against the previous version, and fails or flags anything above a threshold is deterministic. It answers the same way every time, and it catches regressions before they run 500 times a day.
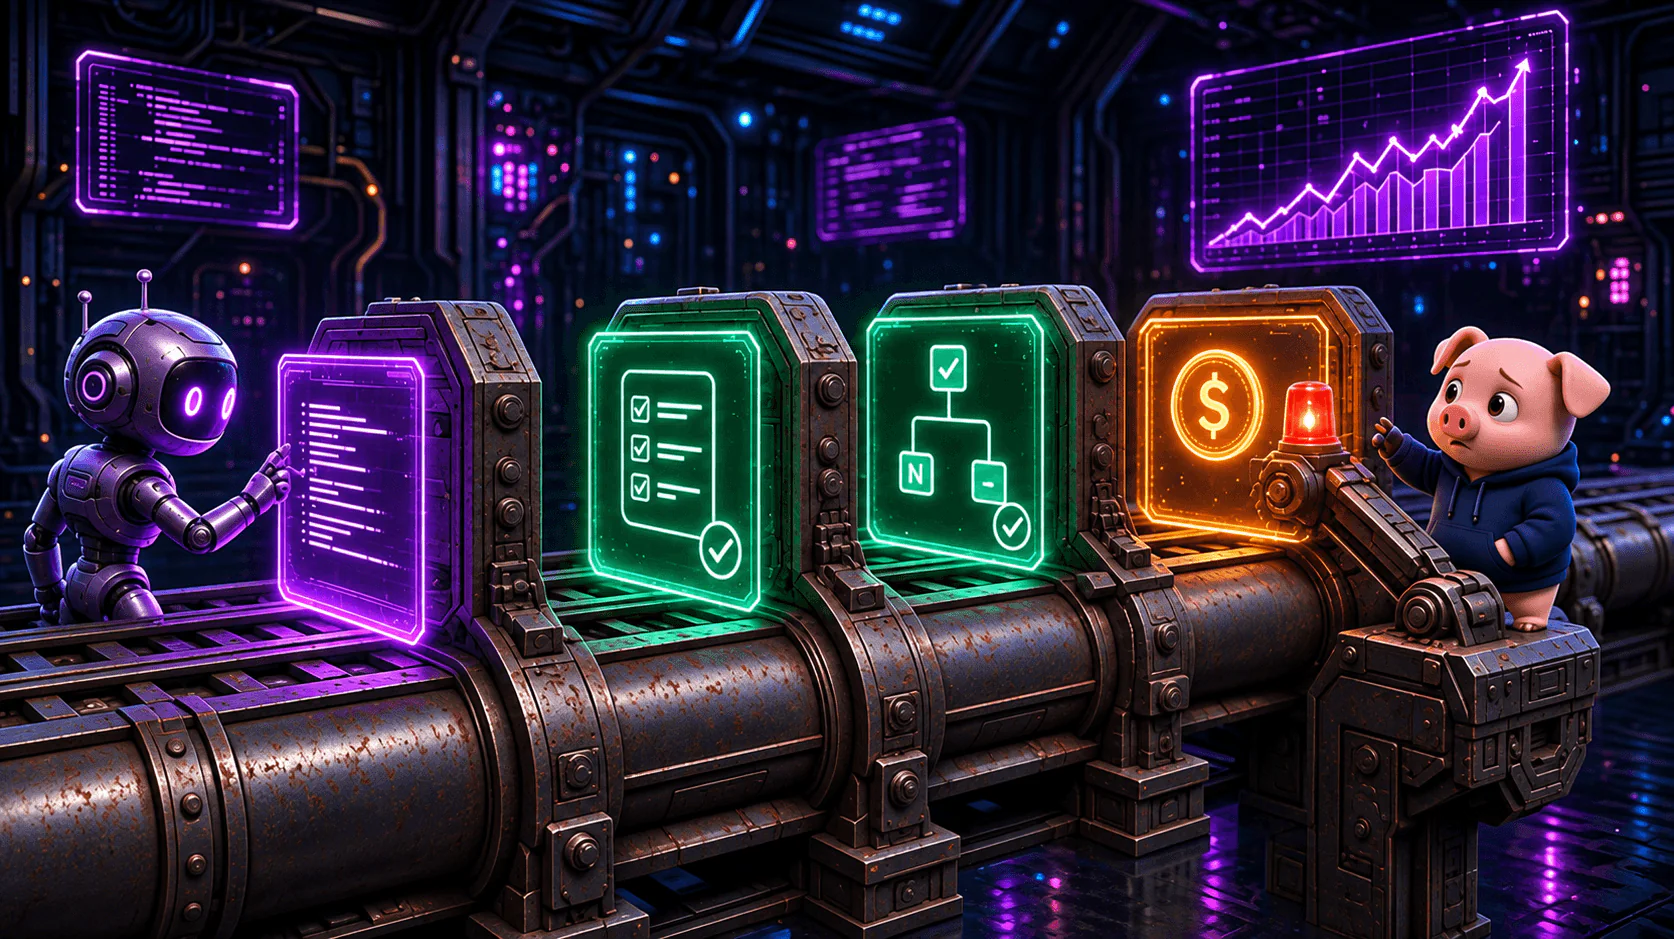
Tests pass, lineage passes, and cost gets flagged for review
Context is what makes agents both right and efficient
I’ve written before that SQL tuning and prompt engineering are really the same discipline: both are about giving the system the right context. The BIRD error analysis of ChatGPT backs that up. The biggest failure modes were about knowing which tables, columns and values matter, not about writing valid SQL.
Cost works the same way. An agent can’t write an efficient query if it doesn’t know a table is clustered by date, that a smaller pre-aggregated model already answers the question, or that a particular warehouse is sized for heavy batch work, not ad hoc lookups. Usage history, lineage, table layout and warehouse configuration are the context that turns a correct query into a sensible one.
So the deterministic layer has two jobs. It checks the agent’s output. And it feeds the agent better input: the metadata that helps it get things right, and cheap, the first time.
Where Seemore fits in
This is the part of the problem we work on at Seemore. We map lineage down to the column level, connect it to actual usage and cost, and look at how warehouses really behave. That combination is useful context for any engineer, human or AI. It shows which assets are expensive, who depends on them, and where a cheaper path already exists. It also surfaces anomalies, like a new workload that suddenly drives up credits, so a costly change shows up quickly instead of at the end of the month.
The bottom line
AI-assisted data engineering works best when the model proposes and deterministic code verifies. Most teams have started building that verification layer for correctness. Cost belongs in it too. Estimate before executing, make warehouse sizing an explicit decision, put hard limits under agent workloads, and treat a big jump in estimated scan as a failed check. Then give agents the context, like lineage, usage and layout, that helps them get it right without the guardrails having to step in.
Frequently asked questions
Can AI-generated SQL be correct but inefficient?
Yes. Correctness and efficiency are separate properties. The BIRD text-to-SQL benchmark scores both, and in a 10-query sample, expert rewrites of correct ChatGPT queries cut run time by about 78% on average with identical results.
How can I estimate Snowflake query cost before running it?
Use EXPLAIN, which compiles the query without executing it and doesn’t need a running warehouse. The plan shows partitions and bytes assigned to each table scan. These are upper-bound estimates, and compilation uses a small amount of cloud services compute.
How do I estimate query cost in BigQuery?
Run a dry run. It validates the query and estimates bytes processed, uses no slots, and isn’t charged. Dry runs on tables with row-level security return 0 bytes, so they can’t be used to estimate cost there.
How do I stop an AI agent from overspending in Snowflake?
Run agent workloads on their own warehouses and assign each a resource monitor with notify and suspend thresholds. Leave a buffer, for example suspend at 90%, and use budgets for serverless and AI services, which resource monitors don’t cover.
What are deterministic guardrails in AI-assisted data engineering?
They are code-based checks that always give the same answer for the same input, such as schema validation, data tests, lineage impact analysis and query cost thresholds. The AI proposes changes, and these checks verify them before they reach production.
Why does context matter for AI-generated SQL?
In an error analysis of ChatGPT on the BIRD benchmark, most errors came from picking the wrong tables, columns or values, not from bad syntax. Giving agents metadata like lineage, usage history, table layout and warehouse sizing helps them produce queries that are both correct and efficient.